Partner Story · in conversation with Gourav Singla. This is a written interview submitted through Submit Your Story. The claims below are his own, presented as they were given to us. No payment was involved.
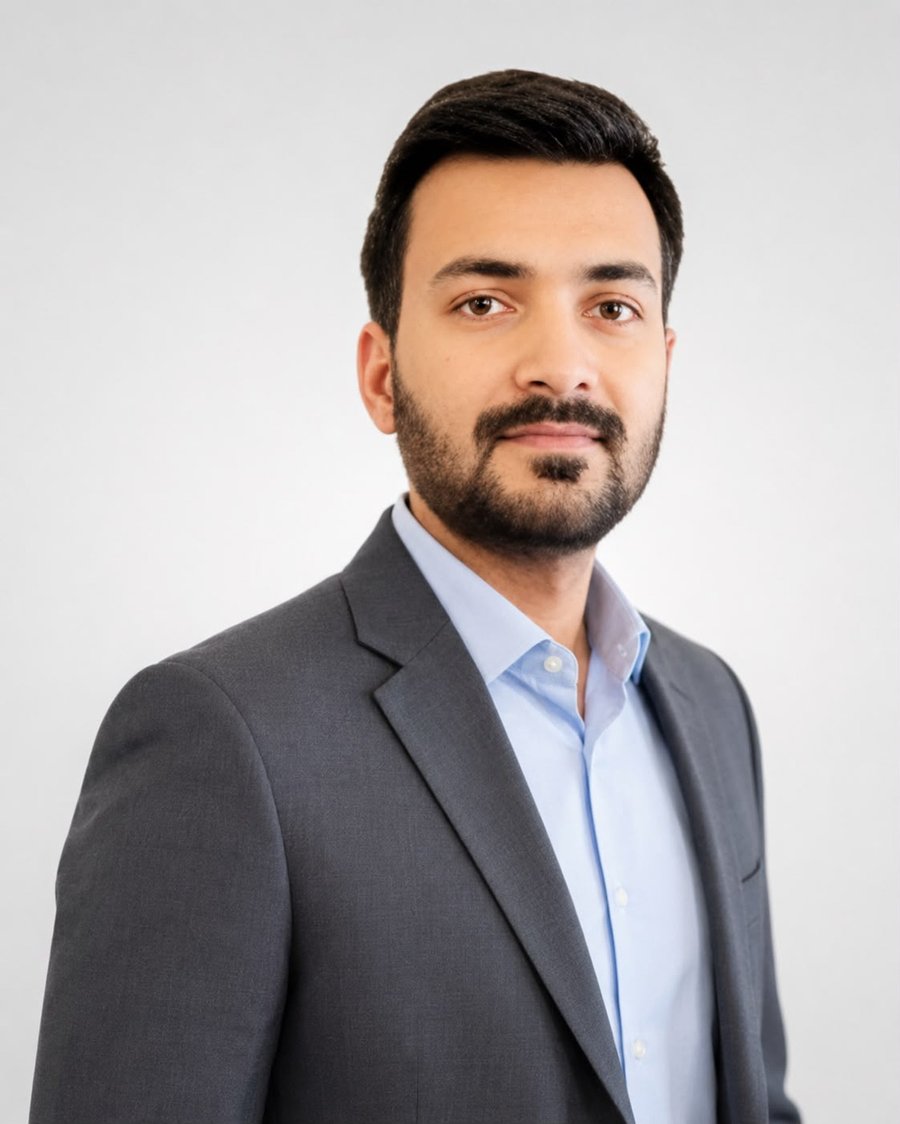
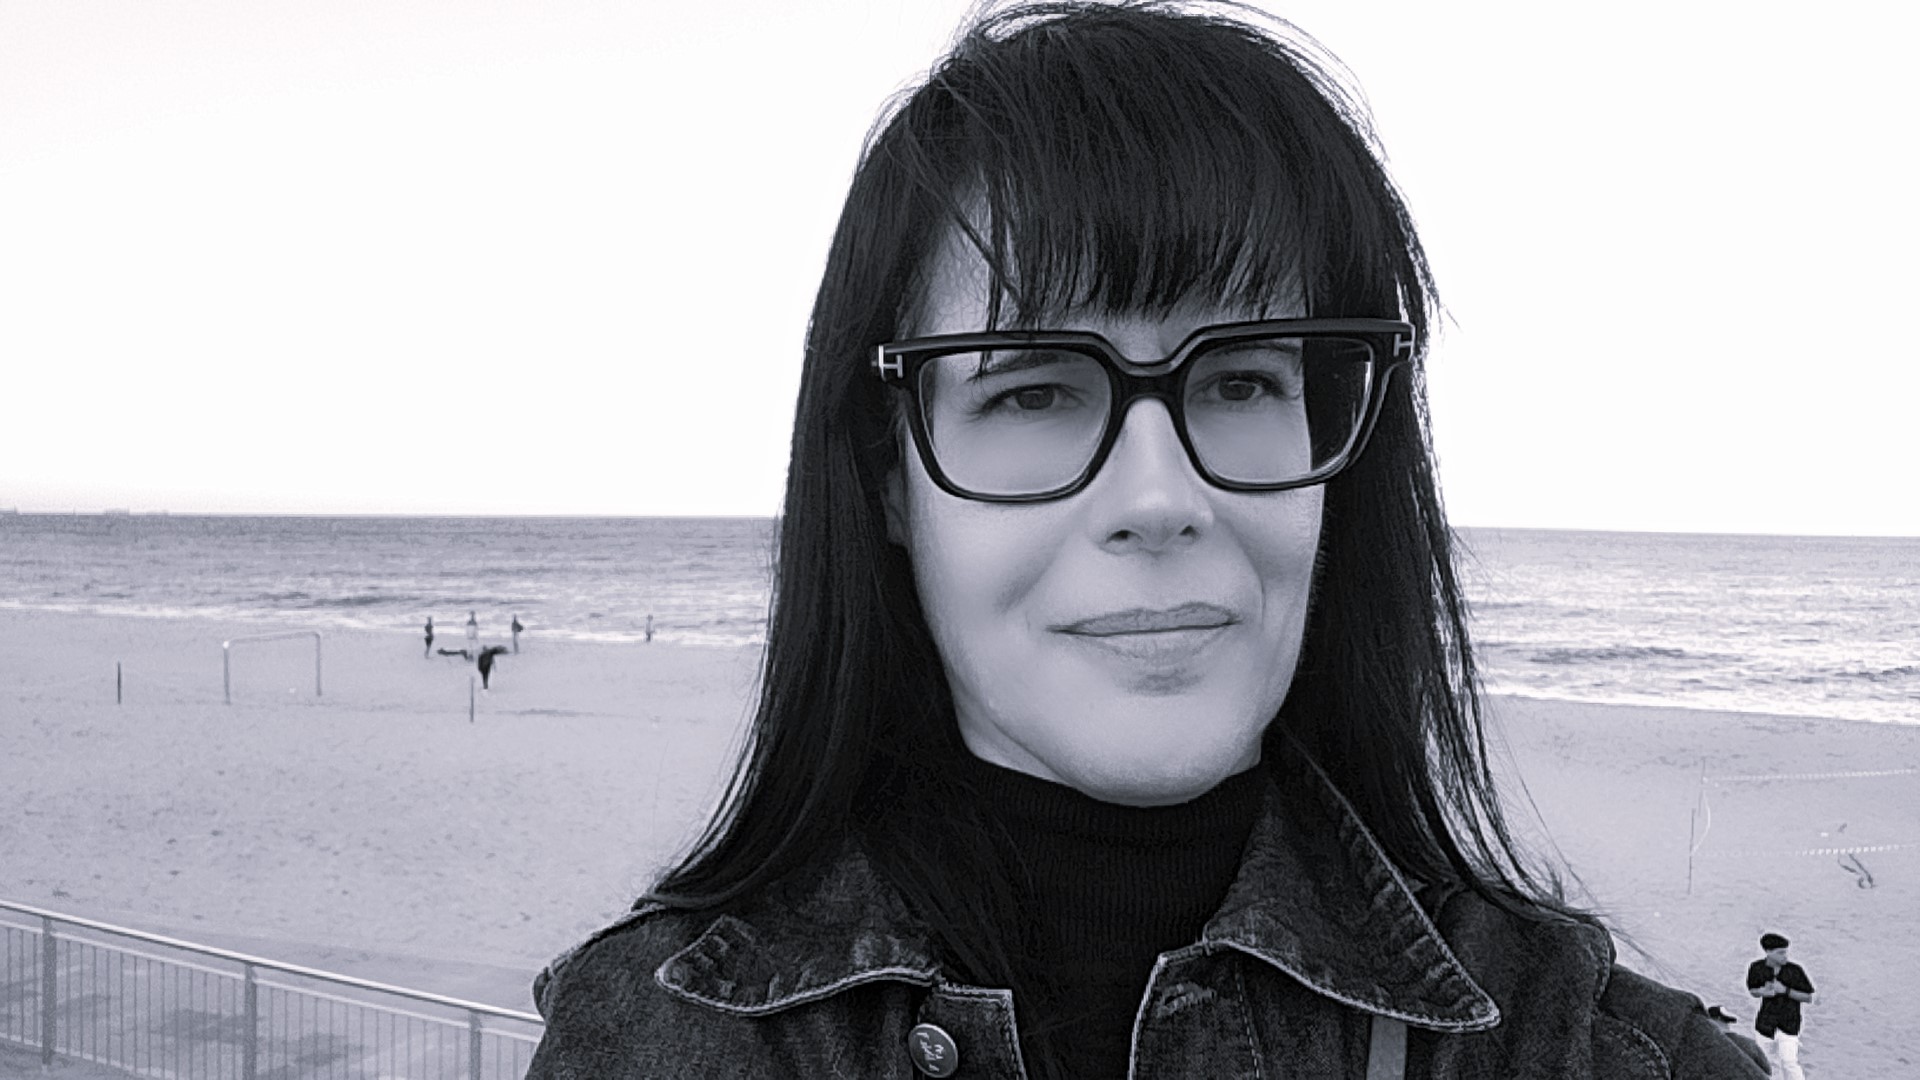
Gourav Singla, creator of SlideMaker.app. Photo: Gourav Singla.
Almost everything written about AI tools is written about a company. This one is not a company, and that is what makes it worth reading.
Gourav Singla works as a computer programmer at Heraeus Covantics, the Heraeus Group operating company that makes high-purity quartz glass for telecoms, medical and semiconductor manufacturing, out of its plant near Atlanta. In his own time he built SlideMaker.app, which turns a topic, a set of notes or an uploaded document into an editable presentation draft.
He is precise about what it is not.
"SlideMaker is not a business or SaaS I operate; it is a public learning project."
No paid plans, no subscriptions, no advertising. By his account nearly 100,000 people in more than 190 countries and territories have used it, and more than 184,000 presentations have been generated, including from university and education organisation email addresses. Those figures are his own and cannot be checked from outside, though the site does carry rate limiting of the kind you put in place when real traffic arrives.
The problem he picked
Turning raw material into a structured deck is slow work, and the shortcuts are worse than they look.
"Most people either start from a blank slide or paste messy text into a generic chatbot and still rebuild the deck by hand."
The question he set out to answer was narrow and useful: can a full pipeline produce a draft good enough that a student, teacher or professional without design skills actually keeps it, rather than starting over.
Where the AI sits
The whole thing is an end to end content pipeline: understand the input, organise it into a logical structure, generate the slide content, produce an editable deck.
He is clear that the interesting engineering is not the generation step.
"The hard research parts are chunking long documents, keeping structure coherent, and making generation reliable under real use."
That distinction is the spine of the project. Asking a model to write ten slides is trivial. Feeding it a forty page PDF, deciding where to cut it, keeping the argument intact across those cuts, and having the result hold together when the file is badly formatted, is where the work lives.
"I built the full pipeline myself as one engineer, not a thin wrapper around a single prompt."
The lesson: generation was the easy part
Asked what building this taught him, Singla gives the answer that made this piece worth publishing.
"Generation was the easy part. Observability was not."
Early on, staging looked fine. Then real users arrived with real files, and the failures were ones no short demo would ever surface: broken structure, bad chunk boundaries, silent pipeline mistakes that produced something plausible and wrong.
"Treat the system around the model as the real research problem."
By that he means the unglamorous half: checks on what comes in, deliberate choices about how documents get cut, handling of refusals and edge cases, and monitoring once it is live. The clearest example of that discipline is the chunking question, which he refused to settle by opinion.
For anyone running an AI feature in production, that is the whole argument compressed into a sentence. The model is the part you buy. Everything that determines whether it works on a Tuesday afternoon with a customer's messy file is the part you build, and it is where the cost and the risk sit.
The measurement that did not go his way
Rather than pick a chunking strategy and defend it, Singla tested four against each other and published the result as a preprint on TechRxiv, IEEE's preprint server, on 29 December 2025. It is called Position-Aware vs Semantic Chunking for Content Generation: Small Gains, Big Trade-offs. He says it is under review at PeerJ Computer Science. A preprint is not peer reviewed, so read it as careful work that nobody else has checked yet.
The setup is straightforward. A corpus of 101 research papers, from just under 3,000 words to nearly 30,000. GPT-4o generating slides from each one. Gemini 2.0 Flash scoring the output against the full source PDF. Four ways of cutting the document up: plain truncation, which simply takes what fits and stops; fixed size first and last; semantic breakpoint, which cuts where the meaning shifts; and position-aware chunking, the sophisticated one, built on the well documented tendency of models to lose material buried in the middle of a long context.
Plain truncation won.
It scored 4.01 out of 5. Semantic chunking came second at 3.98. Fixed size and position-aware tied for last at 3.91. Best to worst was one tenth of a point, roughly two and a half percent. The method he had a theory about finished last, and he published that rather than the version where it worked.
His own conclusion is blunt: the complexity overhead of advanced chunking is not justified by the marginal gain, and practitioners should prefer simple truncation for most use cases.
There is a second finding buried in the paper that is arguably worth more than the first. Every method scored badly on retaining the statistics from the source document, around 2.6 out of 5 across the board. So the thing that actually breaks when you hand a report to a model is not where you cut it. It is that the numbers quietly fail to survive the trip.
For anyone costing out an AI feature, those two results together are worth real money. The engineering weeks budgeted for a clever chunking layer can be spent elsewhere, because on this evidence they buy about two percent. And the effort that was going to go there belongs on verifying that figures came through intact, because that is the failure that reaches a customer as a confident deck with the wrong number in it.
The corpus and pipeline are public under an MIT licence at github.com/gauravsingla05/sop-chunking-pilot, which means the result can be argued with rather than taken on trust.
What free actually means here
There is no revenue line in this story, which is unusual for us, and the economics are still worth stating.
One engineer, working outside a full-time job, serves roughly 100,000 people at his own expense. Every one of those 184,000 presentations consumed model calls that somebody paid for, and that somebody is him. That is a real constraint, and it explains why the engineering emphasis falls where it does: when you personally absorb the compute bill for a free product, efficiency and reliability stop being abstractions.
It also explains the choice to publish the lessons rather than the product. Singla writes publicly about LLM production failures, and ranks among the more read machine learning writers on HackerNoon. The return on this project is not money. It is what he learns and what he can show.
What is next
More work on reliability and document handling, and more writing about what breaks in production. He is open to hearing from readers and practitioners working on applied AI, and the project stays where it is: free, public, and treated as research rather than a company.
SlideMaker is at slidemaker.app.
---
This is a Partner Story: a written interview about a project built with AI, submitted through Submit Your Story and published free of charge. Statements about the project, its users and its results are its own. Building something with AI? Tell us about it.
Would you try this product?